The Switching Cost Nobody's Budgeting For
Nobody buys a quantum computer. They rent qubits.
IBM Quantum, AWS Braket, Azure Quantum, Google Quantum AI. Every serious enterprise trying quantum today is doing it through a cloud API, not a machine in a basement. That is sensible. Cryogenicdilution refrigerators are not a capital expense any CFO wants to explain. But renting qubits creates a procurement problem that almost nobody in enterprise architecture has actually thought through, because it looks like ordinary cloud purchasing and it is not.
Why this is not just another cloud contract
Multi-cloud strategy exists because compute is fungible. A container running on AWS can run on Azure with modest rework. An EC2 instance and an Azure VM do the same job with different names. That fungibility is what gives procurement teams leverage. Threaten to walk, and the vendor knows you actually can.
Quantum hardware breaks that assumption completely. IBM's superconducting qubits, IonQ's trapped ions, and D-Wave's annealers are not interchangeable implementations of the same abstraction. They are different physics. A circuit written for a gate-based superconducting machine does not run on an annealer. Code tuned for IonQ's connectivity does not port cleanly to IBM's topology without a rewrite of the circuit itself, not just the API calls around it.
So, when you pick a QaaS provider, you are not picking a compute vendor. You are picking a physics platform. That is a much bigger decision dressed up in a much smaller-looking contract.
The abstraction layers will not save you, not yet
Frameworks like Qiskit, Cirq, and Amazon's Braket SDK promise portability. In my experience, treating that promise as solved is usually a mistake. These frameworks abstract the syntax. They do not abstract the physics. A circuit that is efficient on one qubit topology can be wildly inefficient on another once the compiler has to insert extra gates to route around connectivity constraints that do not exist on the machine you originally targeted. Your "portable" circuit still needs re-optimisation, sometimes re-design, for every new backend. The abstraction layer reduces your typing effort. It does not reduce your architectural exposure.
Where the lock-in actually bites
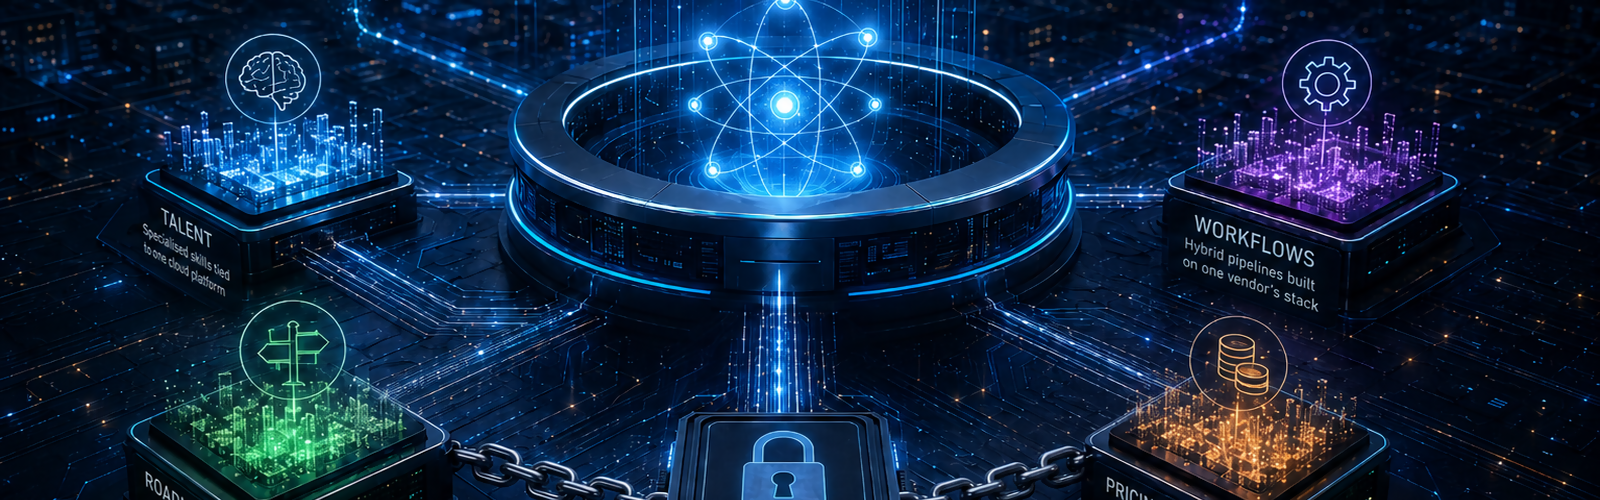
Three places, and none of them show up in the initial pricing conversation.
Talent. Your team learns to write efficient circuits for one vendor's hardware constraints. That expertise does not transfer cleanly. Retraining is not a training course, it is months of relearning how to think about circuit depth and error rates on a different physical substrate.
Hybrid workflow integration. Most real quantum work today is hybrid, classical pre and post-processing wrapped around a quantum subroutine. Once that pipeline is built against a specific vendor's SDK, queueing model, and error mitigation approach, unwinding it is a re-architecture project, not a config change.
Roadmap dependency. You are betting on your chosen vendor's error correction roadmap, not just their current hardware. IBM's path to fault tolerance and IonQ's path to fault tolerance are different bets on different physics. If you have built for one and their scaling curve stalls, you have not lost a supplier. You have lost the assumption your whole quantum strategy was built on.
What this means for procurement
Treat QaaS contracts the way you would treat a bet on a chip architecture, not a bet on a cloud region. That reframes a few things.
Pilot on more than one platform before you commit to production workloads. Not because you will actually run production on two vendors, most organisations will not, but because a second pilot tells you what you'd lose by switching. That is information you cannot get any other way.
Separate your classical and quantum layers cleanly. The classical orchestration code around the quantum subroutine should be vendor-agnostic even if the quantum circuit itself is not. This is standard architecture discipline, but it gets skipped under pilot-project time pressure more often than it should.
Ask vendors directly about their fault tolerance roadmap and timeline, not their current qubit count. Qubit count is the metric vendors want you to compare. It is close to meaningless without knowing the error rate and connectivity that go with it. The roadmap question tells you what you are actually buying into.
Budget for the switching cost as a named line item, even if you never intend to switch. If your finance function cannot see the number, they can't see the risk, and they'll treat quantum procurement like any other SaaS renewal. It is not one.
Part of that switching cost is pricing itself. Every provider prices differently. AWS Braket charges per shot. IBM charges per minute of QPU runtime. Azure Quantum runs a per-program formula with its own minimum charge floor. A circuit that costs a few pounds on one platform can cost sixty times more on another, not because the hardware is worse, but because the pricing model does not map across providers at all. You cannot compare a headline rate and know what you're paying. You have to cost the actual circuit on each platform first. That is not a detail for the finance appendix, it's a reason the switching cost line item needs a proper number behind it, not a guess.
The architect's job here
This is squarely a governance problem, not a technology problem, which is exactly why it is landing on the wrong desk in most organisations. It is being handled as an innovation lab experiment when it should be handled as a strategic sourcing decision with the same scrutiny, you would give an ERP platform choice.
Quantum computing is still years away from being a commodity input you can shop on price. Until it is, every QaaS contract is a physics bet wearing a procurement contract's clothes. Architecture's job is to make sure the business knows which one it is actually signing.